How agentic AI models could (finally) open the door for agent-based modeling in economics

Everyone loves a trilogy, so let’s wrap this up. I told you why agent-based modeling never broke through in economic research. I told you how it could eventually matter. Now I’m going to tell you how AI could, and maybe should, actually make it happen. And as someone who is not fully “AI-pilled”, I will confess that there aren’t that many avenues in which I am particularly excited about AI contributions, particularly in the arts, and even where I see opportunities for great things, I remain pessimistic that Gresham’s Law is going to hit us hard and fast while we are still learning to culturally and institutionally separate the wheat from the slop-riddled chaff.

But let’s put on our more optimistic glasses for the moment and think through what the opportunity for AI to guide agent-based economic modeling into a new (and first) golden age.

First, let’s define a few terms. When I refer to Agentic AI I am specifically considering an LLM model that is capable of autonomously pursuing goals, taking actions, and adapting their behavior in response to new information, all based on a set of pre-defined rules and reward functions and with little to no need for continuing human instruction. When I refer to an Agent-Based Model (ABM) I referring to a computational model of an economic or social system in which individual, heterogeneous agents (consumers, firms, workers, etc) make decisions according to specified behavioral rules, interact with one another and their environment, and collectively generate aggregate economic outcomes.

I don’t want to be wholly redundant with my previous posts, but it’s important to revisit a key theme that ran through both posts: the greatest strength of agent-based modeling is it’s ability to accomodate incredible depth of individual and institutional heterogeneity. Which is a nice way of saying that it is parameter rich. Which is itself a nice way of saying that the models can generate any result without the prospect of credibly investigating the mechanism behind those results and, more importantly, suffiently culling enough noise from them to learn anything about how the world works. For those less familiar with the curse of dimensionality, let me explain.

If a model has 2 parameters you can simply run a grid search of every possible combination of those parameters and observe what kind of outcomes are generated. If you had an agent-based model with 100,000 agents randomly interacting you could still investigate the parameter space by “running” the model 1000 times for each possible combination of parameters and look at the full distribution of outcomes, reporting the mean, variance, and individual quantiles of every outcome of interest for each combination in your grid of parameters. Your results might look like this:
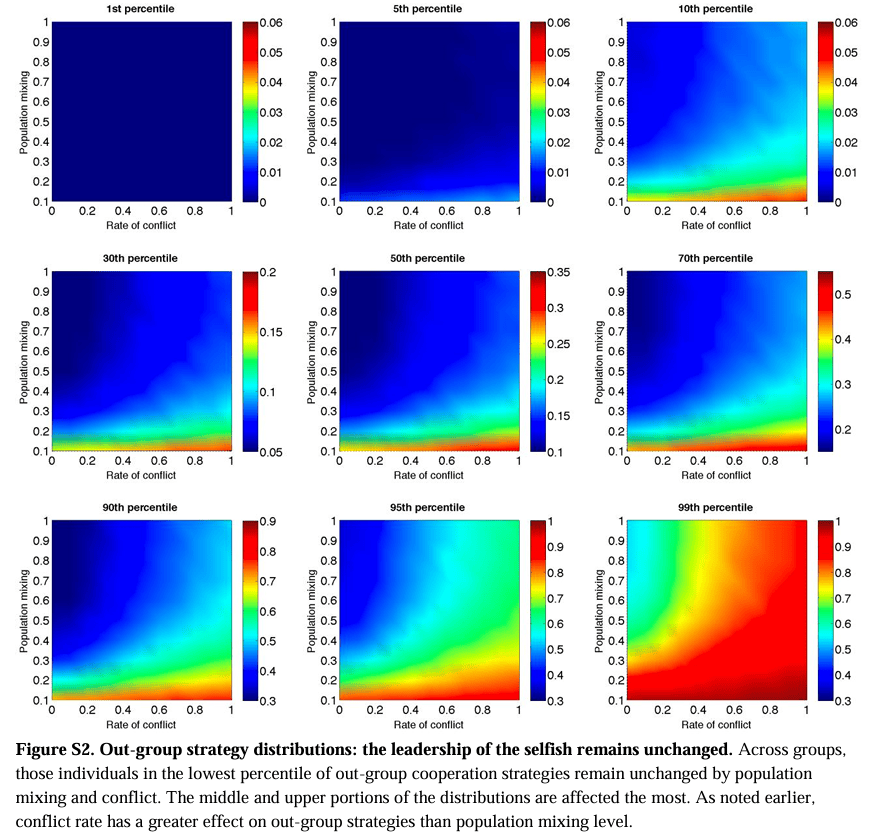
This is a useful way to design and investigate an agent-based model. But you probably already see the problem. Sure, toy models with two parameters are cute, but how do I answer complex economic questions? Toy models can only take us so far. And that’s the rub.

Once you start really start trying to advance economic theory of large, complex economic systems with an agent-based model you’re going to have a lot of visible parameters and lot more less visible parameters. An ABM will be composed of:

  1. Agents (people)
  2. Collectives of agents (firms, clubs, mosques, families, states)
  3. Rules for agent decision-making
  4. Rules for collective decision-making
  5. A context, network, and/or phystical environment with it’s own rules

Every single item on that list will in turn have attributes with both

  1. Initial conditions
  2. Distributional characteristics of those inititial conditions i.e. mean, variance, etc
  3. Are they fixed, exogenously varied, or endogenously varied over time?

Take the first list and add up the total agents, collectives, rules, etc. Then multiply those by each other and by every decision that has to be made in the second list. That number will likley be in the thousands. Congrats, that’s how many true model parameters you have.

With modern macroeconomics, and I am speaking here as a non-macroeconomist, your goal is to reduce that parameter space using basic logic, empirical observation, and modeling decisions that collapse heterogeneity to a small number of representative agents or types. You produce equilibria predictions at each stage of your model and compare them to objective reality. Once the model is sufficiently micro-founded and validated, you can then generate predictions and investigate mechanisms.

The whole point of agent-based modeling, however, is not to collapse the model to a small numbe of representative agents. It’s to endogenously grow aggregate outcomes from the individual endogenous decisions and how, through interactions within the model, they aggregate into predictions for a social system. So what’s the problem? Let’s assume every agent type and collective is characterized by 5 attributes and that each attribute is characterized by 3 statistical properties. Each rule comes with 3 functional variations, characterized by 3 weights each. We’ll then say that there are 5 total agents ( 2 individual types and 3 collectives), for each of whom half of attributes are fixed and half are endogenous. They manner in which they are endogenous has 3 functional variants. If we want to do a true grid search, we’re looking at least at a 5000 combination parameter grid space.

And we are no where near done yet, because we haven’t considered how time works. How steps and sub-steps are ordered. What decisions are synchronous, asynchronous, hieracherially ordered or random. We haven’t considered the social or physical environment What’s you start digging in, your parameter space starts gaining orders of magnitude. And then you realize the real problem is that true grid search of the entire parameter space would take until the heat death of the universe.

What’s the solution to a grid search? A (literal and metaphorical) golden section search. For those unfamiliar, a golden section search reduces the reduces the compuational burder of a grid search by iteratively narrowing the search interval toward an optimum, rather than evaluating every possible parameter combination. What we need is a way to search through a each parameter until we can confidently reduce it to smallest possible window that actually needs to be investigated to properly answer the research question. We need to make decisions.

And that’s what research expertise really is – competently making decisions about what can and should be varied, what can and should be assumed, etc, until we have a tractable question and well-executed research endeavor to answer it. The ABM space is too big for a researcher, however, because too much of the competent execution of research is unobservable, possibly even to the researcher themselves, as the model and the interactions of each decision become intractably complex. Too big for a human researcher. But what about an Agentic AI?

What if we created a base ABM, handed it to an Agentic AI, and told it to recursively evaluate and update the model until the model and the results it generated met a pre-defined set of necessary meta-conditions that the researchers defined as i) a falsified theoretic prediction, ii) generated via observable, definable mechanisms, iii) dependent on a maximal set of modeler decisions, and iv) and independent of set of unlimited, but fully observable modeler decisions?

This is going to take a long, but not necessarily intractable amount of time because we can also define a series of “golden section” adjacent rules that allow the AI to decide with a parmeter, rule, or decicsion is sufficiently irrelevant to ignore or sufficiently constrained to tractably investigate as key outcome determinant or source of outcome sensitivity.

As long as I am giving unsolicited advice to graduate students everywhere interested in agent based modeling, I would suggest forcing such an Agent AI modeler to exclusively use a constrained, pre-defined modeling language or library. Further, you probably want to force a literal, numerical maximum on the number of lines or characters of code. And, lastly, you’ll want to come up outcome rules by which the Agentic AI has to itemize and defend every single deviation of the final model from the base model handed to it. By constraining AI to a limited variety and quantity of coding objects, you are in turn ensuring that the resulting model and the internal mechanism will be transparent to the researchers managing the AI and the broader discipline evaluating them.

Agentic AI offers researchers the ability to iterate through the prospective solution space for modeling problems otherwise intractable via brute force. Further, it allows researchers transparently reveal the instructions that guided the agentic AI dimensions on which the generated model is sensitive to both varied parameters and modeling decisions. It allow for two hierachical levels of meta-research transparency.

That’s what I would be coding write now if I was a PhD student interested in contributing to economics and other social scientific disciplines via agent-based modeling.
Prompting versus fine-tuning

I saw a paper presented at the Economic Science Association meeting that relates to my project on fine-tuning with Josh Foster.

Aligning AI Agents with Economic Preferences in Strategic Environments

Abstract: As large language models (LLMs) increasingly act as autonomous agents in markets and organizations, their behavior in strategic environments becomes economically consequential. We document that off-the-shelf LLM agents exhibit systematic deviations from payoff-sensitive behavior in canonical economic games, including excessive cooperation and limited responsiveness to incentives. We introduce a supervised fine-tuning approach that aligns agent behavior…

LLMs agents get us thinking about humans in a different way (e.g. consciousness and language). We find that fine-tuning alters LLM “behavior.” Prompting matters, too, since everything matters. But fine-tuning is probably more reliable as a way to ensure that a model will act the way you want it to in a wide variety of contexts.

An analogy comes to mind. Prompting is like yelling at your kid to get up so they are not late for school (usually works, but you have to do it every morning). Fine-tuning would be like teaching them to set their own alarm.

Paper Published on Persistent LLM Hallucinations

I am pleased to announce the publication of

“LLM Hallucination of Citations in Economics Persists With Web-Enabled Models”

By Joy Buchanan, Stephen Hill, and Olga Shapoval

ABSTRACT: Despite significant advances since 2023 in large language model (LLM) capabilities and the introduction of web-enabled search functionality, citation hallucination remains a persistent problem in AI-generated academic content. We test GPT-4o, DeepSeek V3, web-enabled GPT-4o, and web-enabled GPT-5.1 across prompts derived from Journal of Economic Literature categories. Using a hierarchical citation validation framework, we find that even an advanced web-enabled model produces non-existent citations. While web-enabled models show improvement over their predecessors, the error rates remain high for scholarly applications. Our findings suggest that the fundamental challenge of citation hallucination persists despite technological advances, with implications for academic integrity and the reliable use of AI in research contexts. We provide an online tool for researchers to run LLMs through the benchmark test using our prompts.

Suggested citation:

Buchanan, J., Hill, S. and Shapoval, O. (2026), LLM Hallucination of Citations in Economics Persists With Web-Enabled Models. Southern Economic J. https://doi.org/10.1002/soej.70069

After some time went by since we published our 2024 paper on this topic and GPT became web-enabled, we thought that this silly problem with hallucinating up fake citations might have gone away. So, we went back to do our count again. We found that a significant number of references are still made up.

I believe that this particular problem of fake citations will go away soon. However, I think the starkness of fake references illustrates something more general about the LLM technology and highlights the importance of verification. Feel free to cite our 2026 paper as evidence that hallucinations are still happening, despite improvements along many margins. Since we started down this track, OpenAI released a paper titled “Why language models hallucinate” at https://openai.com/index/why-language-models-hallucinate/ Excerpt:

Hallucinations persist partly because current evaluation methods set the wrong incentives. While evaluations themselves do not directly cause hallucinations, most evaluations measure model performance in a way that encourages guessing rather than honesty about uncertainty.

You can access our working paper of “LLM Hallucination of Citations in Economics Persists with Web-Enabled Models” on SSRN at https://papers.ssrn.com/sol3/papers.cfm?abstract_id=5318314

We are not in the slow-lane “LLMs are stochastic parrots” group. Stephen Hill does even more with AI in his personal workflow than I do. AI will probably soon qualify for all of the academic prizes we used to award to human writers and scientists. However, as we hand more responsibility over to AI, keep the issue of hallucinations in mind.

Is AI Taking Our Jobs? Signal Boosting Noah Smith

Artificial intelligence is supposed to transform the labor market. Depending on whom you ask, AI is either about to eliminate millions of jobs or usher in a new era of productivity and prosperity. I am reviewing the evidence before I teach an “unemployment” chapter…

I want to give a signal boost to economist Noah Smith, who has been following the emerging evidence about AI and employment at his blog, Noahpinion. His answer, so far, is that the evidence for widespread displacement is weak.

In his September 7 post, “AI keeps stubbornly refusing to take our jobs,” Smith points out a contrast. Many technology executives expect AI to make human workers obsolete, and public opinion surveys from Pew Research Center indicate that Americans share these concerns. Yet employment has held up remarkably well, especially among prime-age workers. AI might still take our jobs soon, but we have not seen widespread displacement yet. Economists have been saying for a long time that automating tasks is not the same thing as eliminating jobs.

In “Automation and New Tasks: How Technology Displaces and Reinstates Labor,” Daron Acemoglu and Pascual Restrepo explain that automation can reduce demand for labor performing particular tasks while also increasing productivity and creating new tasks for workers.

Consider software developers. AI can now write substantial amounts of code. One might conclude that fewer programmers will be needed. But programmers also design systems and decide what software should do. Making code less expensive could expand the amount of software that firms want to produce. Greater productivity may increase rather than decrease the demand for skilled programmers. (my old paper on who wants these jobs is “Willingness to be Paid: Who Trains for Tech Jobs?“)

Smith points readers to Guy Berger’s analysis of software developer employment and reporting on firms that have reconsidered replacing programmers with AI. These examples challenge the assumption that better coding tools necessarily mean fewer coding jobs.

One piece of evidence comes from the U.S. Census Bureau’s Business Trends and Outlook Survey, highlighted by Alex Tabarrok at Marginal Revolution and discussed by Smith. Among firms using AI, 44 percent reported that it supplemented or enhanced existing employee tasks. Ten percent reported that AI performed tasks previously done by employees, while 11 percent reported that AI introduced tasks nobody had previously performed. Most firms reported no employment change attributable to AI.

Smith also highlights research by Ara Kharazian, Jonathon Simon, and David Stevens who find that firms adopting AI tend to expand their employment, including entry-level employment. These findings contrast with the popular narrative that businesses are replacing junior employees with chatbots.

What about young workers?

Continue reading →

Prices as a Map for AI Agents

New from me at EconLog:

Prices as a Map for Minds That Can’t Know Everything

More at the link above. The summary is:

The striking possibility is that increasingly intelligent AI may not make Hayek obsolete. It may give us a new reason to appreciate him. Intelligence does not abolish the economic problem created by dispersed knowledge. A world filled with capable artificial minds may actually contain more decision-makers, more specialization, more private information, and more discoveries that no central intelligence anticipated.

For those minds, as for ours, prices would be a map of a world too complicated for any one mind to know.

Who owns model risk?

Update to readers after doing the CPE (read Internal Audit of AI Agents and Risk for background )

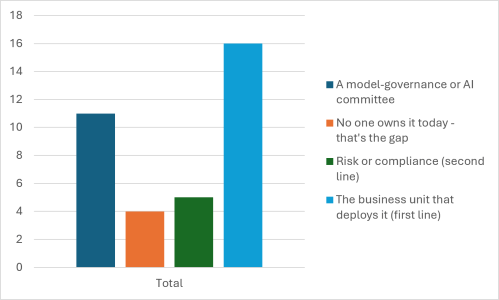
It’s not every day that you get to present to 36 genuine internal auditors for an hour. Not the rowdiest crowd, true to form, but they did answer my poll questions. Many of them work at a regional bank here in Birmingham, AL. Here is the result of an (unscientific) poll from the session:

Opinion Poll: Who should own the risk appetite built into an AI model?

Claude has a better understanding of internal audit procedures than I do and actually helped me come up with the question. The interpretation of the graph is a collaboration between me and Claude, so I will not suppress the em dashes.

The plurality (first line) is the “textbook-correct” instinct — but it’s hollow without capability. Putting ownership on the business unit that deploys the model matches the Three Lines Model cleanly: the first line owns and manages the risks it takes. Good instinct, and worth affirming. The catch is the whole premise of your talk: the deployers usually can’t see the risk preference embedded in their model, let alone measure or set it. So “the business owns it” is right in principle but nominal in practice unless that owner is given the tools to actually recover and govern the appetite. That’s the gap between the poll’s ideal and the room’s reality.

The committee vote (31%) reflects real emerging practice, with a trap. Nearly a third reached for a dedicated AI-governance body — consistent with where NIST’s AI RMF and ISO 42001 point. But a committee can quietly dilute accountability: “everyone owns it” becomes “no one owns it” if it isn’t paired with a clearly accountable first line. Worth naming that risk out loud.

The most important result is the one that isn’t in any single bar: there’s no consensus. If you had asked this room “who owns credit risk?” you’d have gotten a tight, near-unanimous answer. The fact that ownership of a model’s risk appetite scatters across all four choices tells you this accountability is genuinely unsettled in their organizations.

The settled view: credit risk is owned by the first line — the business that originates the exposure. The lending or client-facing unit that decides to extend credit owns the risk of that decision. This is the textbook first-line ownership case, and it’s why credit risk is often the cleanest example used to teach the Three Lines Model.

So, congrats to me and Claude for coming up with a question that split opinion in a room of expert practitioners?

Internal Audit of AI Agents and Risk

Members of the Institute of Internal Auditors know that they can “Join the Birmingham IIA on September 23, 2026 for an insightful CPE webinar featuring Dr. Joy Buchanan… “

I am pleased to get a chance to translate Buchanan and Foster (2026) to an industry audience. I have been reading up on audit controls to prepare.

Some help from Claude with the following: Enterprise risk management rests on a simple discipline: an organization decides how much risk it is willing to take in pursuit of its objectives — its risk appetite — sets tolerances around that level, and then works to keep actual decisions inside those limits. Under COSO ERM, the appetite statement and its tolerances are the structure; the ongoing question is one of conformance. It’s part of the IIA’s AI Auditing Framework and the Three Lines Model: management sets and owns the appetite, risk and compliance build guardrails and monitor, and internal audit provides independent assurance that what the organization actually does matches what it said it would tolerate. A systematic gap between the two is a finding.

For human decision-makers, we’ve built machinery to check this — credit policies, delegated authorities, four-eyes review, documented rationale, an auditable paper trail. We know how to reconstruct whether a loan officer’s or portfolio manager’s judgment stayed inside the lines.

Here is where our paper connects. When an LLM makes a risk-and-return decision — approving credit, weighting a portfolio, ranking procurement options — it too has a risk appetite. But almost none of that oversight infrastructure exists for it. We argue that AI agents are already making decisions with economic consequences and an element of risk.

By showing that the softmax mechanism inside an LLM is McFadden’s random utility model, Buchanan and Foster (2026) establish that the model’s choices reveal a genuine utility function — a measurable risk preference. Our portfolio experiment then recovers the parameters: the slope of the indifference curve we report is the model’s risk appetite, quantified.

I know an Internal Auditor. Some of their old functions will probably get automated. But they have new work to do: auditing the AI agents! Our paper is a step toward both measuring and manipulating the risk appetites of AI agents.

Buchanan, J., & Foster, J. (2026). The innate economic preferences of language models [Preprint]. arXiv. https://doi.org/10.48550/arXiv.2607.26288

Image by Grok. I don’t sell that mug but EWED does have merch at https://shop.spreadshirt.com/economist-writing-every-day/

We Overrate Books

This is per the 2026 discussion of AI “slop” writing.

One of the things I buy at an annual local rummage sale is cheap physical media like books. This year, I picked up a book by a cartoonist who I like and respect. I thought his book would be funny and prescient from the standpoint of the publication date (1995). The book is 250 pages of mostly slop. Humans wrote lots of slop and it got printed by publishers who had a captive audience.

Why did I have such high expectations for a printed book? I think it is because, as of 2026, we are more selective about what we print. A filtering has happened. Many novels printed 100 years ago were junk.

When I think of “books” today, what it really makes me think of is “classics” or the top 0.01% of books.

So, score one point for the slopistas. Human writing was not universally smart or inspiring.

What I hate about slop is seeing it in spaces I used to trust. There was a time when I could log in to LinkedIn and see human writing from people who I had chosen to follow because I like them as people. There was a contract for my attention that is broken with slop.

I sense some push and pull in the algorithm whereby the sites might be suppressing slop, right now, relative to what I was seeing weeks ago. I went to LinkedIn on 7/17/26 to do a slop check and saw none. They might be trying to preserve the lead that James identified earlier this year: The Hot Social Network Is… LinkedIn?

Oddly, one of the worst bot-infested spaces I tread into is Facebook groups about sourdough bread making. I think the space is not important enough for Facebook to police, and the human users are not very sophisticated when it comes to tech. I logged this observation back in January.

Consider this an update to by 2023 post What We Are Learning about Paper Books

Fable on Legibility

Claude Fable is Anthropic’s most capable publicly available “Mythos-class” model. It is optimized for long-running autonomous tasks and deep knowledge work. The roll out of this product has been dramatic. Little people like me have access to it for only two weeks, and I doubt I will be able to afford it thereafter. With my window of access, I posed it the following prompt:

“This article indicates that a much smarter model might not be possible because the universe is opaque. Since Tyler Cowen made this statement, AI has helped people make breakthroughs in math and biology. Write this again in 2026 using the latest state of technology. Is the smartest LLM today much smarter than GPT-4? And is the universe legible?” and I copied in my blog post Is the Universe Legible to Intelligence?

Fable replied in 3 pages of text which you can download as a Word doc here.

One line from Fable’s response: “Notice where the wins clustered: mathematics with checkable proofs, protein structures with experimental ground truth, contest problems with known answers. These are the maximally legible domains — places with a fixed target and a way to verify that you hit it.”

The writing is coherent and contains no obvious hallucinations. Is the answer true, and does it tell the whole truth?

Whenever you read something think about who wrote it, and keep in mind that every author/model has a bias and limitations. In my paper with Will Hickman, we found that just reminding people that a paragraph has an author (whether the author is human or AI) increased the demand for fact checking from readers. LLMs will become more persuasive and closer to (but never completely) correct. Keep reading all things with some skepticism whether they are written by scientists, politicians, or AI.

Regardless, there is definitely such a thing as making the known world more legible to AI today. Thus, people are talking about increasing funding for data availability and the possible demise of the “research paper.”

Research papers are more like stories than facts. The demand for stories is not going away, but I definitely cannot predict the future of the write-for-pay scientist.

AI, potentially, could go and get its own new data, instead of waiting for humans to archive it. Thus, the self-improving AI might take us beyond the current models… unless they run up against something that is not legible to intelligence…

The Empire Strikes Back against AI Cheating

People are considering whether university evaluations can survive in the AI age. Hollis Robbins wrote on Substack: “How to limit unauthorized AI use in the classroom“

Robbins emphasizes class size and teaching load against the time of an instructor.  An instructor teaching 4 sections with 100 students each is very limited in their ability to monitor and prosecute AI teaching. It’s worse if this instructor is on a temporary contract.

Limited eyes and hands and human attention really are a constraint here, at least for now. Some people see AI tools in the hands of students as the end of education itself.

I have been tweeting my replies to this:

I don’t do remote exams, but I hear about improvements to remote proctoring technology. The arms race is not over.

Technology goes both ways. The phone students were using to cheat are now being marshalled as a “second camera” for remote test proctoring. Instructors are going to largely win this year if they take current technology seriously, for multiple choice and short answer evaluations.

The commercial Respondus program has just added Word extensions. This technology already exists and can run on the students’ laptops.

Right now, a clever student might still be able to shift their carbon-based eyes to a direction where the answer is displayed illicitly. And the instructor’s eyes can only monitor so many eyes. This is all so 2024. This conversation may be over soon. Human students can be placed under the supervision of machine eyes. Right now, we are still dealing with issues of false positives when machines flag students for cheating, but the machines are improving.

I believe that the roads will eventually be dominated by machine drivers and their unblinking eyes. Humans might drive cars for fun in the hinterlands, but it will no longer be considered a serious thing humans to do for work. Monitoring student cheating will become like truck driving. Human eyes are on the way out. We are going to become more cheat-proof than college has ever been before.

As a college professor, that will have implications for my job, although I can imagine a not-completely-negative future. Maybe I could do more fun work with students because the work of proctoring will be handled automatically. I have spent many many hours constructing tests that would be hard to cheat on and watching students take them. I take cheating seriously, and all the faculty at my business school work hard to protect the value of our degree. I predict that this will become a trivial part of teaching within 10 years.

Will students respond with various forms of hacking and deep fakes against such a system? Maybe. So far, in any arms race, Uncle Sam has been winning in the end for a century now.

If there is a will to do so, we could even bring back the research paper by having students work on a monitored computer that does not let them use AI to write. (We could almost do that already, but perhaps the true limiting factor is that, as I like to say, readers are that which is scarce.)

[Credit to my colleagues Art Carden and Anna Leigh Stone who have talked with me about test proctoring this semester.]