Abstract: As large language models (LLMs) increasingly act as autonomous agents in markets and organizations, their behavior in strategic environments becomes economically consequential. We document that off-the-shelf LLM agents exhibit systematic deviations from payoff-sensitive behavior in canonical economic games, including excessive cooperation and limited responsiveness to incentives. We introduce a supervised fine-tuning approach that aligns agent behavior…
LLMs agents get us thinking about humans in a different way (e.g. consciousness and language). We find that fine-tuning alters LLM “behavior.” Prompting matters, too, since everything matters. But fine-tuning is probably more reliable as a way to ensure that a model will act the way you want it to in a wide variety of contexts.
An analogy comes to mind. Prompting is like yelling at your kid to get up so they are not late for school (usually works, but you have to do it every morning). Fine-tuning would be like teaching them to set their own alarm.
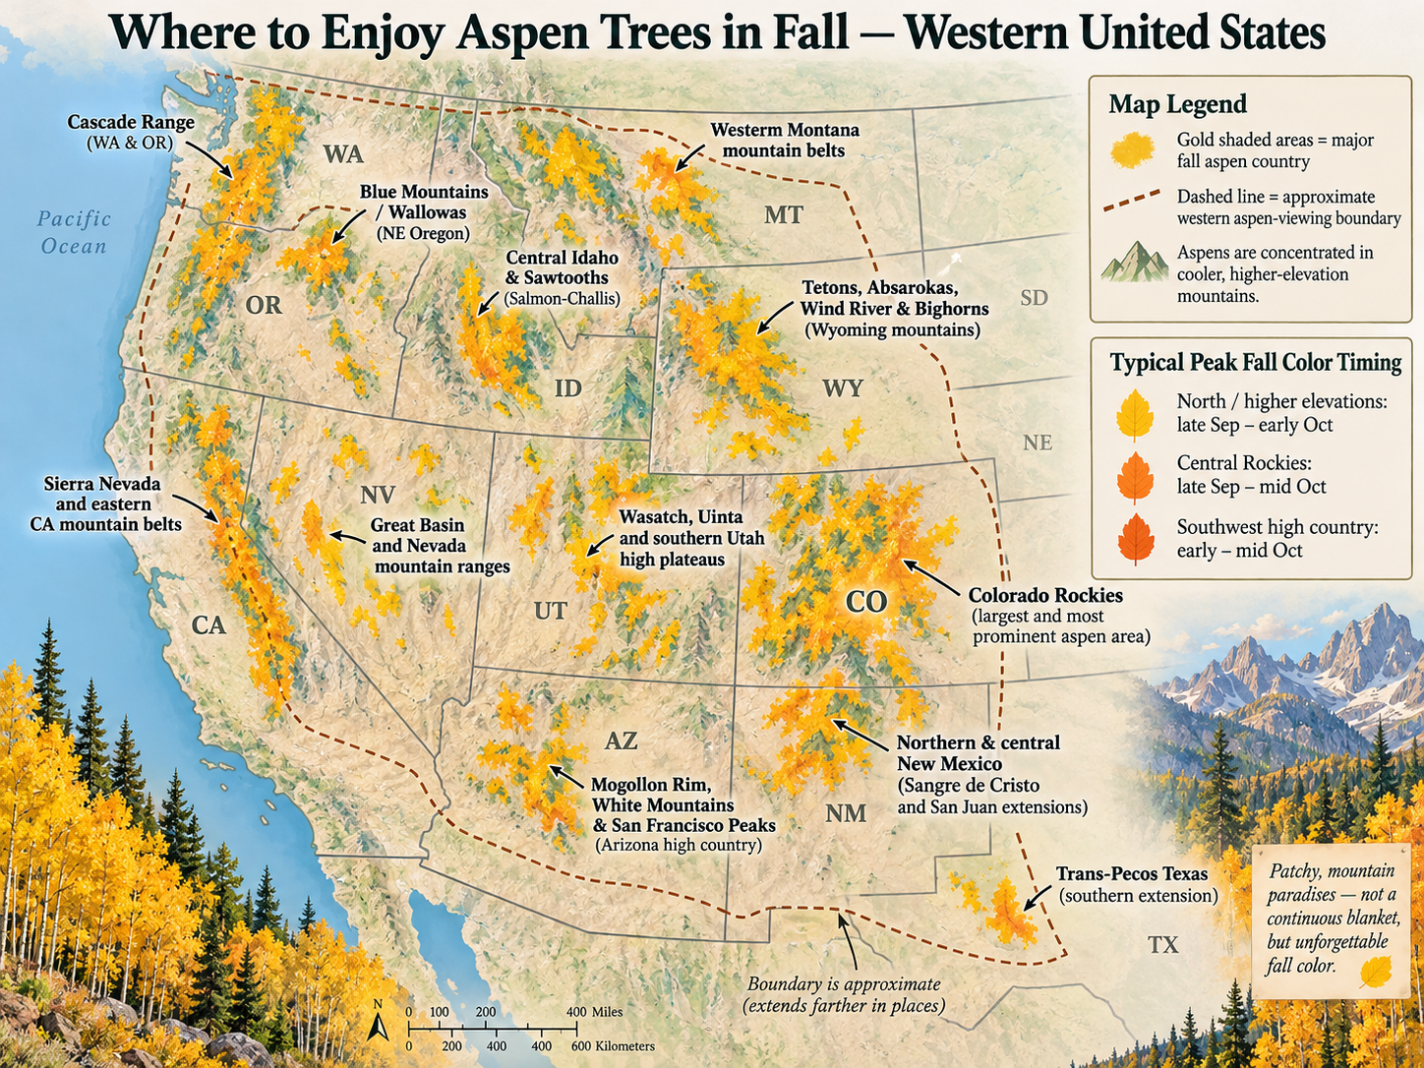
Even though I have been to the American West and even lived in California for 5 years, my Fall Break 2026 trip to New Mexico was my first encounter with Aspen trees in the Fall. I am the last person to discover this but happy to be on the train. The piercing blue sky of the High Desert makes a stunning frame for the gold trees. Double the beauty by going into local art galleries in Santa Fe to see paintings of the same. I found my phone camera roll to be disappointing compared to the real thing. ChatGPT helped me produce this map for you.
Some people have a similar encounter with New England in the fall, but I already knew about that.
Fall in the Southeast means getting a break from the heat and being able to enjoy sunshine again outside of water sports. I don’t mean to undersell it. There are many really nice days in the Southeast, it’s just hard to plan ahead of time when they will occur.
ABSTRACT: Despite significant advances since 2023 in large language model (LLM) capabilities and the introduction of web-enabled search functionality, citation hallucination remains a persistent problem in AI-generated academic content. We test GPT-4o, DeepSeek V3, web-enabled GPT-4o, and web-enabled GPT-5.1 across prompts derived from Journal of Economic Literature categories. Using a hierarchical citation validation framework, we find that even an advanced web-enabled model produces non-existent citations. While web-enabled models show improvement over their predecessors, the error rates remain high for scholarly applications. Our findings suggest that the fundamental challenge of citation hallucination persists despite technological advances, with implications for academic integrity and the reliable use of AI in research contexts. We provide an online tool for researchers to run LLMs through the benchmark test using our prompts.
Suggested citation:
Buchanan, J., Hill, S. and Shapoval, O. (2026), LLM Hallucination of Citations in Economics Persists With Web-Enabled Models. Southern Economic J. https://doi.org/10.1002/soej.70069
After some time went by since we published our 2024 paper on this topic and GPT became web-enabled, we thought that this silly problem with hallucinating up fake citations might have gone away. So, we went back to do our count again. We found that a significant number of references are still made up.
I believe that this particular problem of fake citations will go away soon. However, I think the starkness of fake references illustrates something more general about the LLM technology and highlights the importance of verification. Feel free to cite our 2026 paper as evidence that hallucinations are still happening, despite improvements along many margins. Since we started down this track, OpenAI released a paper titled “Why language models hallucinate” at https://openai.com/index/why-language-models-hallucinate/ Excerpt:
Hallucinations persist partly because current evaluation methods set the wrong incentives. While evaluations themselves do not directly cause hallucinations, most evaluations measure model performance in a way that encourages guessing rather than honesty about uncertainty.
We are not in the slow-lane “LLMs are stochastic parrots” group. Stephen Hill does even more with AI in his personal workflow than I do. AI will probably soon qualify for all of the academic prizes we used to award to human writers and scientists. However, as we hand more responsibility over to AI, keep the issue of hallucinations in mind.
Artificial intelligence is supposed to transform the labor market. Depending on whom you ask, AI is either about to eliminate millions of jobs or usher in a new era of productivity and prosperity. I am reviewing the evidence before I teach an “unemployment” chapter…
I want to give a signal boost to economist Noah Smith, who has been following the emerging evidence about AI and employment at his blog, Noahpinion. His answer, so far, is that the evidence for widespread displacement is weak.
In his September 7 post, “AI keeps stubbornly refusing to take our jobs,” Smith points out a contrast. Many technology executives expect AI to make human workers obsolete, and public opinion surveys from Pew Research Center indicate that Americans share these concerns. Yet employment has held up remarkably well, especially among prime-age workers. AI might still take our jobs soon, but we have not seen widespread displacement yet. Economists have been saying for a long time that automating tasks is not the same thing as eliminating jobs.
Consider software developers. AI can now write substantial amounts of code. One might conclude that fewer programmers will be needed. But programmers also design systems and decide what software should do. Making code less expensive could expand the amount of software that firms want to produce. Greater productivity may increase rather than decrease the demand for skilled programmers. (my old paper on who wants these jobs is “Willingness to be Paid: Who Trains for Tech Jobs?“)
One piece of evidence comes from the U.S. Census Bureau’s Business Trends and Outlook Survey, highlighted by Alex Tabarrok at Marginal Revolution and discussed by Smith. Among firms using AI, 44 percent reported that it supplemented or enhanced existing employee tasks. Ten percent reported that AI performed tasks previously done by employees, while 11 percent reported that AI introduced tasks nobody had previously performed. Most firms reported no employment change attributable to AI.
Smith also highlights research by Ara Kharazian, Jonathon Simon, and David Stevens who find that firms adopting AI tend to expand their employment, including entry-level employment. These findings contrast with the popular narrative that businesses are replacing junior employees with chatbots.
The striking possibility is that increasingly intelligent AI may not make Hayek obsolete. It may give us a new reason to appreciate him. Intelligence does not abolish the economic problem created by dispersed knowledge. A world filled with capable artificial minds may actually contain more decision-makers, more specialization, more private information, and more discoveries that no central intelligence anticipated.
For those minds, as for ours, prices would be a map of a world too complicated for any one mind to know.
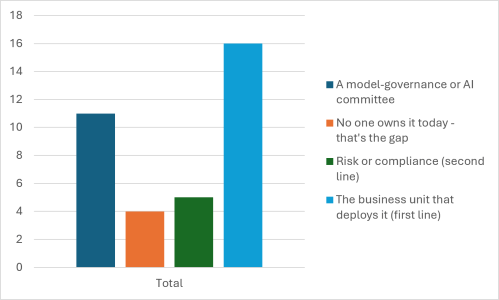
It’s not every day that you get to present to 36 genuine internal auditors for an hour. Not the rowdiest crowd, true to form, but they did answer my poll questions. Many of them work at a regional bank here in Birmingham, AL. Here is the result of an (unscientific) poll from the session:
Opinion Poll: Who should own the risk appetite built into an AI model?
Claude has a better understanding of internal audit procedures than I do and actually helped me come up with the question. The interpretation of the graph is a collaboration between me and Claude, so I will not suppress the em dashes.
The plurality (first line) is the “textbook-correct” instinct — but it’s hollow without capability. Putting ownership on the business unit that deploys the model matches the Three Lines Model cleanly: the first line owns and manages the risks it takes. Good instinct, and worth affirming. The catch is the whole premise of your talk: the deployers usually can’t see the risk preference embedded in their model, let alone measure or set it. So “the business owns it” is right in principle but nominal in practice unless that owner is given the tools to actually recover and govern the appetite. That’s the gap between the poll’s ideal and the room’s reality.
The committee vote (31%) reflects real emerging practice, with a trap. Nearly a third reached for a dedicated AI-governance body — consistent with where NIST’s AI RMF and ISO 42001 point. But a committee can quietly dilute accountability: “everyone owns it” becomes “no one owns it” if it isn’t paired with a clearly accountable first line. Worth naming that risk out loud.
The most important result is the one that isn’t in any single bar: there’s no consensus. If you had asked this room “who owns credit risk?” you’d have gotten a tight, near-unanimous answer. The fact that ownership of a model’s risk appetite scatters across all four choices tells you this accountability is genuinely unsettled in their organizations.
The settled view: credit risk is owned by the first line — the business that originates the exposure. The lending or client-facing unit that decides to extend credit owns the risk of that decision. This is the textbook first-line ownership case, and it’s why credit risk is often the cleanest example used to teach the Three Lines Model.
So, congrats to me and Claude for coming up with a question that split opinion in a room of expert practitioners?
Members of the Institute of Internal Auditors know that they can “Join the Birmingham IIA on September 23, 2026 for an insightful CPE webinar featuring Dr. Joy Buchanan… “
I am pleased to get a chance to translate Buchanan and Foster (2026) to an industry audience. I have been reading up on audit controls to prepare.
Some help from Claude with the following: Enterprise risk management rests on a simple discipline: an organization decides how much risk it is willing to take in pursuit of its objectives — its risk appetite — sets tolerances around that level, and then works to keep actual decisions inside those limits. Under COSO ERM, the appetite statement and its tolerances are the structure; the ongoing question is one of conformance. It’s part of the IIA’s AI Auditing Framework and the Three Lines Model: management sets and owns the appetite, risk and compliance build guardrails and monitor, and internal audit provides independent assurance that what the organization actually does matches what it said it would tolerate. A systematic gap between the two is a finding.
For human decision-makers, we’ve built machinery to check this — credit policies, delegated authorities, four-eyes review, documented rationale, an auditable paper trail. We know how to reconstruct whether a loan officer’s or portfolio manager’s judgment stayed inside the lines.
Here is where our paper connects. When an LLM makes a risk-and-return decision — approving credit, weighting a portfolio, ranking procurement options — it too has a risk appetite. But almost none of that oversight infrastructure exists for it. We argue that AI agents are already making decisions with economic consequences and an element of risk.
By showing that the softmax mechanism inside an LLM is McFadden’s random utility model, Buchanan and Foster (2026) establish that the model’s choices reveal a genuine utility function — a measurable risk preference. Our portfolio experiment then recovers the parameters: the slope of the indifference curve we report is the model’s risk appetite, quantified.
I know an Internal Auditor. Some of their old functions will probably get automated. But they have new work to do: auditing the AI agents! Our paper is a step toward both measuring and manipulating the risk appetites of AI agents.
I am going to Korea next year. I look forward to being able to relay travel observations. Here’s what I can say so far.
I have several distinct personal points of connection to Korea through my family, my husband’s family, and my next-door neighbor here in Alabama. There is a George Mason U. campus in Korea. I hope to explore all of those connections when I go.
KPop Demon Hunters was an absolute phenomenon on Netflix last year. Every school child in America, across every race and state, knew the songs. As for the soundtrack, I determine: “Golden” – correctly rated “Soda Pop” – overrated “What it Sounds Like” – underrated And what is interesting in September of 2026 is how fast the whole thing died out. Trends come and then they really go in the monoculture (is this the “unicontext”?).
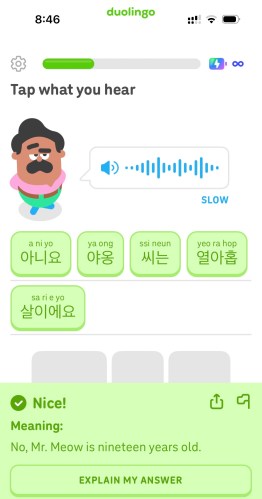
I am learning Korean by doing one lesson per day on Duolingo. Progress is slow, partly because I do not expect to need to become fluent ever. I am enjoying this. I have frittered away a good number of hours on cognitive trivia like computer Solitaire and Wordle. On the margin, I encourage a few of you English speakers to make learning a Non-Romance Language your new game. I have also used Duolingo to try to brush up on Spanish and French, but it’s fun to enter a totally different mindset altogether. It’s also difficult and might be frustrating if I had a higher bar for my performance.
If any readers have a connection in Seoul, please let me know.
If using ChatGPT or an API in 2023, you might have followed the advice “turn the temperature down” when you wanted a more serious answer. That is going out of date. The following is a collaboration between me and Grok to lay this out simply:
What temperature was
Imagine the model is always choosing the next word from a long list of options, ranked from “very likely” to “weird but possible.” Temperature changes how adventurous that choice is.
Low temperature: almost always pick the obvious next word. Answers feel steady, repetitive, “corporate.” Good when there is basically one right output, like extracting a date from a contract.
High temperature: more willing to pick a less obvious word. Answers feel livelier but sometimes incorrect.
On older products you could often set this yourself.
What thinking level is
Newer models (Gemini 3, OpenAI’s reasoning models) do extra work before they talk to you. They draft a private scratchpad: break the problem into steps, check themselves, then write the answer you see. You don’t see the scratchpad even though you pay for it. That hidden draft is the “thinking.”
Thinking level (sometimes called reasoning effort) is not “how random should the next word be?” It is “how long is the model allowed to work on that draft?”
Low / minimal: answer quickly and cheaply. Fine for “what’s the status of ticket 1842?”
High: spend more time (and more tokens) on hard things — a gnarly spreadsheet, a multi-step plan, a tricky piece of code.
A childhood friend and Facebook contact of mine pleaded to her friends, “How do people afford multiple children?”
I checked up on her and saw delightful pictures of a second child who, one way or another, they are now financially supporting along with that firstborn girl, in 2026. I obviously won’t post her family photos, but they took a summer trip to Yosemite National Park that looked something like this
Image by Grok
Based on how she felt about supporting a second child, I would be surprised if they have a third, a “big family.” Two is about where most people can still afford to take trips across the country in the summer.
This caused me to reflect on Dolly Parton, who we all miss. The U.S. flag is at half-staff in recognition of Dolly’s passing.
Part of her charming narrative is the fact that she was born into poverty. Famously, Dolly grew up with 11 siblings in a two-room Tennessee cabin. I doubt their family made it out to Yosemite.
So, with some help from ChatGPT, I inquired about the Total Fertility Rate of those Parton children. In one generation, everything dramatically changed. The number of children born to the Parton clan ranges from three to zero. Chat writes:
Dolly and her five sisters appear to have had only about six biological children among them—an average of roughly one child per woman. Dolly herself had none. Including their brothers, the twelve Parton siblings seem to have produced only about sixteen children altogether.
The Parton family therefore compresses a major American demographic change into just two generations. Avie Lee had twelve children; her daughters averaged about one each.