Paper Published on Persistent LLM Hallucinations

I am pleased to announce the publication of

“LLM Hallucination of Citations in Economics Persists With Web-Enabled Models”

By Joy Buchanan, Stephen Hill, and Olga Shapoval

ABSTRACT: Despite significant advances since 2023 in large language model (LLM) capabilities and the introduction of web-enabled search functionality, citation hallucination remains a persistent problem in AI-generated academic content. We test GPT-4o, DeepSeek V3, web-enabled GPT-4o, and web-enabled GPT-5.1 across prompts derived from Journal of Economic Literature categories. Using a hierarchical citation validation framework, we find that even an advanced web-enabled model produces non-existent citations. While web-enabled models show improvement over their predecessors, the error rates remain high for scholarly applications. Our findings suggest that the fundamental challenge of citation hallucination persists despite technological advances, with implications for academic integrity and the reliable use of AI in research contexts. We provide an online tool for researchers to run LLMs through the benchmark test using our prompts.

Suggested citation:

Buchanan, J., Hill, S. and Shapoval, O. (2026), LLM Hallucination of Citations in Economics Persists With Web-Enabled Models. Southern Economic J. https://doi.org/10.1002/soej.70069

After some time went by since we published our 2024 paper on this topic and GPT became web-enabled, we thought that this silly problem with hallucinating up fake citations might have gone away. So, we went back to do our count again. We found that a significant number of references are still made up.

I believe that this particular problem of fake citations will go away soon. However, I think the starkness of fake references illustrates something more general about the LLM technology and highlights the importance of verification. Feel free to cite our 2026 paper as evidence that hallucinations are still happening, despite improvements along many margins. Since we started down this track, OpenAI released a paper titled “Why language models hallucinate” at https://openai.com/index/why-language-models-hallucinate/ Excerpt:

Hallucinations persist partly because current evaluation methods set the wrong incentives. While evaluations themselves do not directly cause hallucinations, most evaluations measure model performance in a way that encourages guessing rather than honesty about uncertainty.

You can access our working paper of “LLM Hallucination of Citations in Economics Persists with Web-Enabled Models” on SSRN at https://papers.ssrn.com/sol3/papers.cfm?abstract_id=5318314

We are not in the slow-lane “LLMs are stochastic parrots” group. Stephen Hill does even more with AI in his personal workflow than I do. AI will probably soon qualify for all of the academic prizes we used to award to human writers and scientists. However, as we hand more responsibility over to AI, keep the issue of hallucinations in mind.
Malwarebytes Poll: Public Fascination with ChapGPT Has Turned to Suspicion

ChatGPT and related AI have been all the rage these past few months. Among other things, “AI” became the shiny object that companies have dangled before investors, rocketing upward the shares of the “Magnificent Seven” large tech stocks.

However, a recent poll by computer security firm Malwarebytes notes a marked turn in the public’s attitude towards these products:

It seems the lustre of the chatbot-that’s-going-to-change-everything is starting to fade….

When people explored its capabilities in the days and weeks after its launch, it seemed almost miraculous—a wonder tool that could do everything from creating computer programs and replacing search engines, to writing students’ essays and penning punk rock songs. Its release kick-started a race to disrupt everything with AI, and integrate ChatGPT-like interfaces into every conceivable tech product.

But those that know the hype cycle know that the Peak of Inflated Expectations is quickly followed by the Trough of Disillusionment. Predictably, ChatGPT’s rapid ascent was met by an equally rapid backlash as its shortcomings became apparent….

A new survey by Malwarebytes exposes deep reservations about ChatGPT, with optimism in startlingly short supply. Of the respondents familiar with ChatGPT:

  • 81% were concerned about possible security and safety risks.
  • 63% don’t trust the information it produces.
  • 51% would like to see work on it paused so regulations can catch up.

The concerns expressed in the survey mirror the trajectory of the news about ChatGPT since its introduction in November 2022.

As EWED’s own Joy Buchanan has been pointing out specifically with regard to citations for research papers (here, here, and in the Wall Street Journal), ChatGPT tends to “hallucinate”, i.e., to report things that are not simply true. In the recent working paper “GPT-3.5 Hallucinates Nonexistent Citations: Evidence from Economics” , she warns of the possibility of a vicious spiral of burgeoning falsehoods, where AI-generated errors which are introduced into internet content such as research papers are then picked up as “learning” input into the next generation of AI training.

Real-world consequences of ChatGPT’s hallucinations are starting to crop up. A lawyer has found himself in deep trouble after filing an error-ridden submission in an active court case. Evidently his assistant, also an attorney, relied on ChatGPT which came up with a raft of “citations to non-existent cases.” Oops.

And now we have what is believed to be “the first defamation lawsuit against artificial intelligence.” Talk show host Mark Walters filed a complaint in Georgia which is:

…asking for a jury trial to assess damages after ChatGPT produced a false complaint to a journalist about the radio host.  The faux lawsuit claimed that Mr. Walters, the CEO of CCW Broadcast Media, worked for a gun rights group as treasurer and embezzled funds.

…Legal scholars have split on whether the bots should be sued for defamation or under product liability, given it’s a machine — not a person — spreading the false, hurtful information about people.

The issue arose when an Australian mayor threatened to sue the AI company this year over providing false news reports that he was guilty of a foreign bribery scandal.

Wow.

Thousands of AI experts and others have signed an open letter asking: “Should we let machines flood our information channels with propaganda and untruth? Should we automate away all the jobs, including the fulfilling ones? Should we develop nonhuman minds that might eventually outnumber, outsmart, obsolete and replace us? Should we risk loss of control of our civilization?”.    The letter states that “Such decisions must not be delegated to unelected tech leaders. Powerful AI systems should be developed only once we are confident that their effects will be positive and their risks will be manageable.”    It therefore urges  “all AI labs to immediately pause for at least 6 months the training of AI systems more powerful than GPT-4…If such a pause cannot be enacted quickly, governments should step in and institute a moratorium…AI labs and independent experts should use this pause to jointly develop and implement a set of shared safety protocols for advanced AI design and development that are rigorously audited and overseen by independent outside experts.”

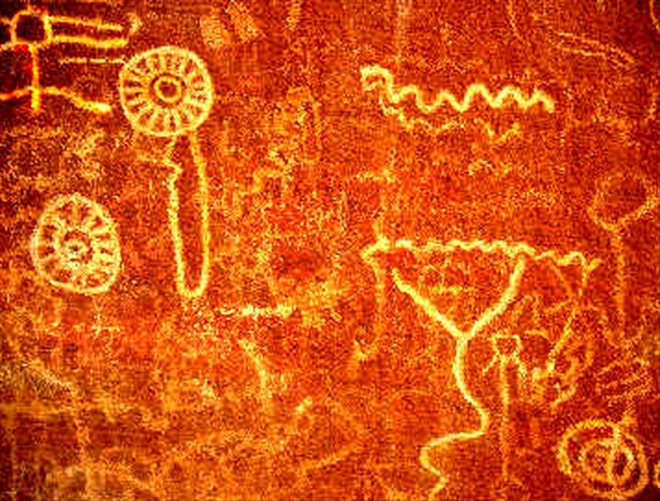
Oh, the irony. There is reason to believe that our Stone Age ancestors were creating unreal images like this:

whilst stoned on peyote, shrooms, or oxygen deprivation. And here we are in 2023, with the cutting edge in information technology, running on the fastest specially-fabricated computing devices, and we get…hallucinations.