Artificial intelligence and the market in mitigating rational ignorance

Greenville, South Carolina does a pretty admirable job trying to lower the cost of being informed about local governance.
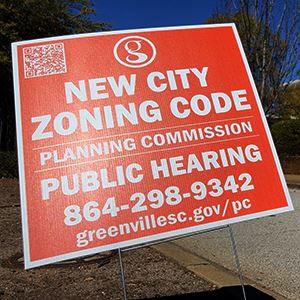
There’s no getting around the fact, however, that I remain pretty rationally ignorant of what’s happening in my neighborhood. This stands despite my being both a local homeowner and an economist who is intellectually invested in the idea that obstacles to housing construction are a major cause of a wide variety of social ills. The reason for my ignorance remains the same as most peoples: I’m busy.

Many cities have blogs and subreddits that one can follow to keep abreast of local policy. What I really need, though, is a paid liason who’s entire job is to absorb and distill all of these political currents into a single information digest consumable as a quarterly email. Decent chance there are at least 100 homeowners in my area who would pay for such a service. Should you offer such a service?

No, you should not. Why? Because you’d be rendered obsolete within a two years because I’m pretty sure I’m going to be able have a large language model produce exactly that email for me, probably for free.

Everyone keeps looking for “the big use case” for AI and LLMs. Allow me to suggest instead that the big use case is in fact thousands of micro use cases, those tasks for whom we could all use a 3-5 hours per year personal assistant, but such a relationship simply isn’t a net gain given the fixed costs of a retaining an assistant. Some of the big use cases for early AI’s will, in this sense, be similar to Uber or Airbnb: they reduce the fixed costs and transaction costs of personal services.

For me, one of those first personal services provided by Chat GPT or it’s closest rival may simply be telling me who to vote for:

“I am a X year old homeowner in zip code XXXXX. I am single/married with X children of ages [X….X]. I earned X dollars last year. What should I vote for and against in the upcoming election on November 11th?”

Tyler vs Matt on SVB Bailouts

Having nothing original to say about the topic du jour, I will highlight two different takes for your consideration.

Tyler in Can the SVB crisis be solved in the longer run?

An unwillingness to guarantee all the deposits would satisfy the desire to penalize businesses and banks for their mistakes, limit moral hazard, and limit the fiscal liabilities of the public sector. Those are common goals in these debates. Nonetheless unintended secondary consequences kick in, and the final results of that policy may not be as intended.

Once depositors are allowed to take losses, both individuals and institutions will adjust their deposit behavior, and they probably would do so relatively quickly. Smaller banks would receive many fewer deposits, and the giant “too big to fail” banks, such as JP Morgan, would receive many more deposits. Many people know that if depositors at an institution such as JP Morgan were allowed to take losses above 250k, the economy would come crashing down. The federal government would in some manner intervene – whether we like it or not – and depositors at the biggest banks would be protected.

In essence, we would end up centralizing much of our American and foreign capital in our “too big to fail” banks. That would make them all the more too big to fail. It also might boost financial sector concentration in undesirable ways.

To see the perversity of the actual result, we started off wanting to punish banks and depositors for their mistakes. We end up in a world where it is much harder to punish banks and depositors for their mistakes.

Matt Y in America needs more giant banks

The problem is, what happens if PNC fails? PNC is the sixth largest bank in the country with over $500 billion in assets. That makes it dramatically smaller than the Big Four banks that are informally labeled “too big to fail” and formally classified as Global Systemically Important Banks (GSIBs).

Tyler wants to see more banks, and not just “Too big to fail” banks. In as many industries as possible, we prefer less concentration. More competition tends to be good for customers and leads to more innovation. Tyler is more comfortable in the messiness that midsize banks cause, or at least he presents that as a necessary evil.

Matt is arguing against more banks, because Silicon Valley Bank wasn’t pre-designated as too big to fail, and yet we are in crisis mode now.

Matt might say that I’m mischaracterizing his argument. Specifically, Matt said that tiny banks are fine because they are small enough for a private company to buy in times to distress. Matt does not explicitly call for fewer banks. However, I think the demise of the mid-size bank would almost certainly result in fewer banks total.

To give a full picture of the arguments being made this week, here’s someone arguing against bailing out SVB.

And here is the EWED SVB material to date:

Jeremy: It’s Never Good News When Deposit Insurance is in the News

Mike: Estimating the effects of a slow news cycle

For real-time updates, follow Jeremy on Twitter:

Self-Replicating Machines: A Practical Human Response

Currently, we have software that can write software. What about physical machines that can produce physical machines? Indeed, what about machines that can produce other machines without human direction?

First of all, machines-building machines (MBM) still require resources: energy, transportation, time, and other inputs. A well-programmed machine that self-replicates quickly can grow in number exponentially. But where would the machines get the resources that enable self-replication? They’d have to purchase them (or conquer the world sci-fi style). Where would a machine get the resources to make purchases of necessary inputs? The same place that everyone else gets them.

Continue reading →

Life Expectancy By State 1990-2019

I’m making a panel of historical life expectancy data by state available here:

Life Expectancy By State 1990-2019

It covers the years 1990 to 2019 for every US state, and has life expectancy at birth, age 25, and age 65. It includes breakdowns by sex and by race and ethnicity, though the race and ethnicity breakdowns aren’t available for every state and year.

This is one of those things that you’d think would be easy to find elsewhere, but isn’t. The CDC’s National Center for Health Statistics publishes state life expectancy data, but only makes it easily available back to 2018. The United States Mortality DataBase has state life expectancy data back to 1959, but makes it quite hard to use: it requires creating an account, uses opaque variable names, and puts the data for each state into a different spreadsheet, requiring users who want a state panel to merge 50 sheets. It also bans re-sharing the data, which is why the dataset I present here is based on IHME’s data instead.

The IHME data is much more user-friendly than the CDC or USMDB, but still has major issues. By including lots of extraneous information and arranging the data in an odd way, it has over 600,000 rows of data; covering 50 states over 30 years should only take about 1,500 rows, which is what I’ve cleaned and rearranged it to. IHME also never actually gives the most basic variable: life expectancy at birth by state. They only ever give separate life expectancies for men and women. I created overall life expectancy by state by averaging life expectancy for men and women. This gives people any easy number to use, but a simple average is not the ideal way to do this, since state populations aren’t exactly 50/50, particularly for 65 year olds. If you’re doing serious work on 65yo life expectancy you probably want to find a better way to do this, or just use the separate male/female variables. You might also consider sticking with the original IHME data (if its important to have population and all cause mortality by age, which I deleted as extraneous) or the United States Mortality DataBase (if you want pre-1990 data).

Overall though, my state life expectancy panel should provide a quick and easy option that works well for most people.

Here’s an example of what can be done with the data:

If states are on the red line, their life expectancy didn’t change from 1990 to 2019. If a state were below the red line, it would mean their life expectancy fell, which done did (some state names spill over the line, but the true data point is at the start of the name). The higher above the line a state is, the more the life expectancy increased from 1990 to 2019. So Oklahoma, Mississippi, West Virginia, Kentucky and North Dakota barely improved, gaining less than 1.5 years. On the other extreme Alaska, California, New York improved by more than 5 years; the biggest improvement was in DC, which gained a whopping 9.1 years of life expectancy over 30 years. My initial thought was that this was mainly driven by the changing racial composition of DC, but in fact it appears that the gains were broad based: black life expectancy rose from 65 to 72, while white life expectancy rose from 77 to 87.

You can find other improved datasets on my data page, and once again this life expectancy data is here: Life Expectancy By State 1990-2019

It’s Never Good News When Deposit Insurance is in the News

As you may have heard, there have been a few bank failures in the US in the past week. This has led ordinary people to start refreshing their memory about exactly what “deposit insurance” is and what it means for them. It has also led regulators, politicians, and economists to start refreshing their memory about the social purpose of deposit insurance, which is to stabilize the banking system. There are lots of aspects of the bank failures and deposit insurance to consider, but I think we can all agree that when ordinary people are thinking about this topic, bad things are going on.

While I can’t find a systematic survey of economists on this topic, my guess is that most economists would agree with the statement “on balance, deposit insurance promotes stability in the financial system.”

But there is a minority view, and one with (in my opinion) considerable historical support. Deposit insurance could potentially be destabilizing, since it has the potential (like any form of insurance) to create moral hazard. By lowering the cost of making mistakes, we would expect more mistakes. The cost need not be lowered all the way to zero for moral hazard to be a problem (bank owners still have some skin in the game), but the cost is certainly lower. These problems may be even more of a threat to the financial system than other areas of life covered by insurance.

That’s the theory. What’s the evidence?

My favorite paper on this topic is a 1990 article by Charles Calomiris called “Is Deposit Insurance Necessary? A Historical Perspective.” Not only does it conclude that deposit insurance isn’t necessary, but even more: it may be destabilizing. (You can also read a version of the article intended for a more general audience that Calomiris wrote for the Chicago Fed.)

Continue reading →

Don’t Look Back

On the Positivity Blog are no less than “67 Don’t Look Back Quotes to Help You Move on and Live Your Best Life”. Some of these sayings from notable folks include:

“Never look back unless you are planning to go that way.”
– Henry David Thoreau

“If you want to live your life in a creative way, as an artist, you have to not look back too much. You have to be willing to take whatever you’ve done and whoever you were and throw them away.”
– Steve Jobs

“There are far, far better things ahead than any we leave behind.”
– C.S. Lewis

“Don’t cry because it’s over, smile because it happened”  

– attributed to Dr. Seuss, though that attribution is heavily disputed

The Random Vibez offers another “60 Don’t Look Back Quotes To Inspire You To Move Forward”’ including “Don’t look back. You’ll miss what’s in front of you” and “I tend not to look back. It’s confusing”.   The Bible would add sayings such as, “Let your eyes look straight ahead; fix your gaze directly before you” (Proverbs 4:25); Paul wrote to the Philippians, “One thing I do: Forgetting what is behind and straining toward what is ahead, I press on toward the goal to win the prize for which God has called me”.

The Landy-Bannister Statue

What put me in mind of this whole theme of not looking back was seeing a bronze statue involving Roger Bannister. Sports buffs, and most educated people who are over 60, will know that he was the first man to break the four-minute mile. During many previous decades of trying, no human had been able to run that fast that long: that is a velocity of 15 miles per hour, sustained for a full four minutes. That is like a full sprint for most people, or a moderate bicycling speed. 

Bannister found that he was naturally a fast runner, and he employed scientific principles in his training. (He was a medical student at the time, and went on to become a noted research neurologist).  On May 6, 1954 Bannister finally cracked the four-minute mile, with a 3:59.4 time. As may be imagined, the crowd went wild.

Records, however, are made to be broken, and just 46 days later a rival runner, John Landy, ran the mile in just 3:57.9 to become the world’s fastest man. A few months after that Bannister and Landy ran head-to-head in the August, 1954 Commonwealth games in Vancouver. Landy was in the lead nearly the whole way, with a ten-yard lead by the end of the third lap. Bannister then started his signature kick and managed to catch up with Landy on the final bend. Landy must have heard footsteps, and at the end of the race glanced over his left shoulder to gauge Bannister’s position. That distraction slowed him just enough to allow Bannister to power past him on his right side. Landy’s time was still a respectable 3:59.6, but Bannister won with 3:58.8. Both runners later agreed that Landy would have won if he had not looked back. More on that race, including link to video of it, here.

This finish of this “Miracle Mile” race was immortalized by a larger-than-life bronze statue by Vancouver sculptor Jack Harman. Landy later quipped, “”While Lot’s wife was turned into a pillar of salt for looking back, I am probably the only one ever turned into bronze for looking back.”

Estimating the effects of a slow news cycle

A the moment, the collapse of Silicon Valley Bank is the dominant story in the news cycle. It seemed like a big deal to me at first, then less of a big deal, then of enormous consequence again. At the moment, my estimation has settled into “A negative event that will hurt some people but will only be of long run consequence unless it yields sufficiently bad new economic policy out of it i.e. receive a bailed that entirely shields them from consequences. But honestly I don’t know. My estimation really shouldn’t move your priors too much unless you were previously sitting at one of the extremes of “Nothing actually happened” or “This is the beginning of a new Great Depression”. I’m quite confident neither of those is correct. If you want a solid accounting, read Noah Smith’s post. I think he probably nailed it.

What I do want to consider is enthusiasm within the “take marketplace” for breathless concerns this was the beginning of a financial meltdown, a desperate situation that calls for a federal bailout, the beginning of inevitable hyperinflation, evidence even that catastrophic consequences of “wokeism” for <checks notes> risk hedging within bank portfolios. All of these seem somewhere between overwrought and stupid, all got a non-trivial amount of oxygen within the news cycle. [UPDATE: Depositors were maintained through federal liquidity, shareholders were not bailed out. Seems pretty reasonable to me.] Many takes were no doubt motivated by personal assets at stake or economic hobbyhorses, but I’m more concerned with how much traction they got than their origin stories.

So here’s a research idea so quarter-baked I haven’t even looked on google scholar to see if it’s been done, let alone would work. What is the relationship between a slow news cycle and pessimistic affect in event coverage? Here’s I’d go about it:

  1. Create an idex of news story variation. Variation in news coverage is an indicator that nothing is happening. When important things happen, they get covered alot, which means there is less variation in stories across outlets.
  2. Run an natural language algorithm for measuring “pessimistic affect” i.e. doomerism in news stories.
  3. Estimate the relationship between lagged news story variation and current pessimistic affect.
  4. ?
  5. Publish

The hypothesis is simple: when the news cycle is slow, outlets and pundits have an incentive to not just hype the importance of any event, but accentuate it’s potential negative consequences going forward so they can keep talking about it.

That’s it. Thats the idea. I hope you will include me in the acknowledgments when accepting your various research awards and accolades.

Be Posting Always

James wrote about our posting philosophy in “Always Be Posting”. The regularity is the point. This strategy is not our original idea, but this specific manifestation of blogging is a kind of experiment that we are running in front of everyone. I’ll add a few comments on this practice.

  1. I blogged more than once a week at first. Although I believe in the benefits of writing, once a week is the right amount for me.
  2. Tyler recently asked Brad Delong about Substack. Delong says, “Substacking is blogging, except that Substacking is blogging where you have explicit permission to send things to people’s email inboxes, and also to have a rather large tip jar.” Tyler mentioned that Substack posts tend to be longer. Delong admits, “I thought blogging was more fun.” Delong thinks longer posts are better because they fight the trend of short posts that I earlier called Poastmodernism. I would say that if you are going to blog regularly for free like we do, it should be fun. That is also what Tyler said when I asked him if young people should blog regularly in “The New Econ Bloggers.”
  3. If you are going to blog, you might wonder when you should start. Society seems obsessed with young geniuses today. I started blogging before tenure but not when I was very young. I should not have started any earlier. Think about the research that shows your brain is still forming until you are about 25. If Leonardo DiCaprio would date you, then be careful about what you say on the internet. What I would hope for teens or undergraduates is that they would have smart safe people to bounce ideas off of. You certainly need to practice writing and questioning. Even though it nearly kills me at the end of every semester, I assign papers in my classes, because I believe that college students should be writing. I was and am lucky to have teachers and friends who I talk to one-on-one when I want to try out ideas. You should be “posting” in the most abstract sense when you are young, but a private paper journal is not a bad place to start.
  4. When the internet first started, I don’t think anyone would have guessed how much content people would create for free. People are posting so much. Despite worries that media pirating would lead to too little content creation, we have more content than ever.

Something fun about regular short posts is that you can put a stake down and then revisit it years later. Here are two of my posts that have turned out well.

  1. In 2022, I went to Disney World for the first time. Ross Douthat criticized Disney World in his book The Decadent Society. I like the book, but I thought that he clearly hadn’t been there. I wrote a whole blog about Disney being the opposite of infrastructure stagnation. Here is Ross now with his New York Times column saying “Wow, I had never actually been there, and the physical infrastructure is amazing.”
  2. In 2021, I wrote “I encourage parents to read fantasy with children. I see a lot of children’s books that promote science or STEM-readiness… Those games that try to trick 5-year-olds into “programming” are less valuable than reading and discussing fantasy stories… What your child will need to be able to do when they are 20 is read and comprehend a textbook that explains a totally new technology that no one alive today understands. Then they will need to think of creative ways to apply that technology to real world problems.” The developments in ChatGPT are making this look pretty good, even earlier than I expected.

We are a posting kind of species.

The Allure of Overconfidence

I say what economists are supposed to say. I tell everyone who will listen that they should invest in index funds and then don’t check their balances. I explain that abnormal returns stem from abnormal information. Individuals are unlikely to have abnormal insight about publicly traded companies because other people have more time and resources to find that information. Further, even if a professional has abnormal insight, it’s not likely to persist over time. Index funds get around the problem of idiosyncratic risk and the brevity of abnormal insight by riding on the back of the more informed. I say all of this and I believe it in my heart.

I teach macroeconomics and I’ve published about asset volatility. I know more about inflation and the macroeconomy than the typical investor. From mid-2020 through now the S&P500 has gained 11.3% annually. My personal return has been 21% annually. It’s true, however, that the first half of 2022 was rough. But I can’t help but feel happy and confident.*

Continue reading →

Regulatory Costs and Market Power

That’s the title of a blockbuster new paper by Shikhar Singla. The headline finding is that increased regulatory costs are responsible for over 30% of the increase in market power in the US since the 1990’s. That’s a big deal, but not what I found most interesting.

One big advance is simply the data on regulation. If you want to measure the effect of regulation on different industries, you need to come up with a way to measure how regulated they are. The crude, simple old approach is to count how many pages of regulation apply to a broad industry. The big advance of Mercatus’ RegData was to use machine learning to identify which specific industry is being discussed near “restrictive words” in the Code of Federal Regulation that indicate a regulatory restriction is being imposed. But not all regulatory words (even restrictive ones) are created equal; some impose very costly restrictions, most impose less costly restrictions, and some are even deregulatory. Singla’s solution is to take the government’s estimates of regulatory costs and apply machine learning there:

This paper uses machine learning on regulatory documents to construct a novel dataset on compliance costs to examine the effect of regulations on market power. The dataset is comprehensive and consists of all significant regulations at the 6-digit NAICS level from 1970-2018. We find that regulatory costs have increased by $1 trillion during this period.

The government’s estimates of the costs are of course imperfect, but almost certainly add information over a word-count based approach. Both approaches agree that regulation has increased dramatically over time. How does this affect businesses? Here’s what’s highlighted in the abstract:

We document that an increase in regulatory costs results in lower (higher) sales, employment, markups, and profitability for small (large) firms. Regulation driven increase in con- centration is associated with lower elasticity of entry with respect to Tobin’s Q, lower productivity and investment after the late 1990s. We estimate that increased regulations can explain 31-37% of the rise in market power. Finally, we uncover the political economy of rulemaking. While large firms are opposed to regulations in general, they push for the passage of regulations that have an adverse impact on small firms

More from the paper:

an average small firm faces an average of $9,093 per employee in our sample period compared to $5,246 for a large firm

a 100% increase in regulatory costs leads to a 1.2%, 1.4% and 1.9% increase in the number of establishments, employees and wages, respectively, for large firms, whereas it leads to 1.4%, 1.5% and 1.6% decrease in the number of establishments, employees and wages, respectively for small firms when compared within the state-industry-time groups. Results on employees and wages provide evidence that an increase in regulatory costs creates a competitive advantage for large firms. Large firms get larger and small firms get smaller.

The fact that large firms benefit while small firms are harmed is what drives the increase in concentration and market power.

What I like and dislike most about this paper is the same thing: its a much better version of what Diana Thomas and I tried to do in our 2017 Journal of Regulatory Economics paper. We used RegData restriction counts to measure how regulation affected the number of establishments and employees by industry, and how this differed by firm size. I wish I had thought of using published regulatory cost measures like Singla does, but realistically even if I had the idea I wouldn’t have had the machine learning chops to execute it. The push to quantify what “micro” estimates mean for economy-wide measures is also excellent. I hope and expect to see this published soon in a top-5 economics journal.

HT: Adam Ozimek